Memory Bandwidth, Not Just Compute, Speeds Up AI Chatbots
When a chatbot types out its answer word by word, the speed you see is often limited by how fast a chip can move data, not by how fast it can calculate. That is why memory bandwidth has become one of the most important specifications in AI hardware.
Every token needs the whole model
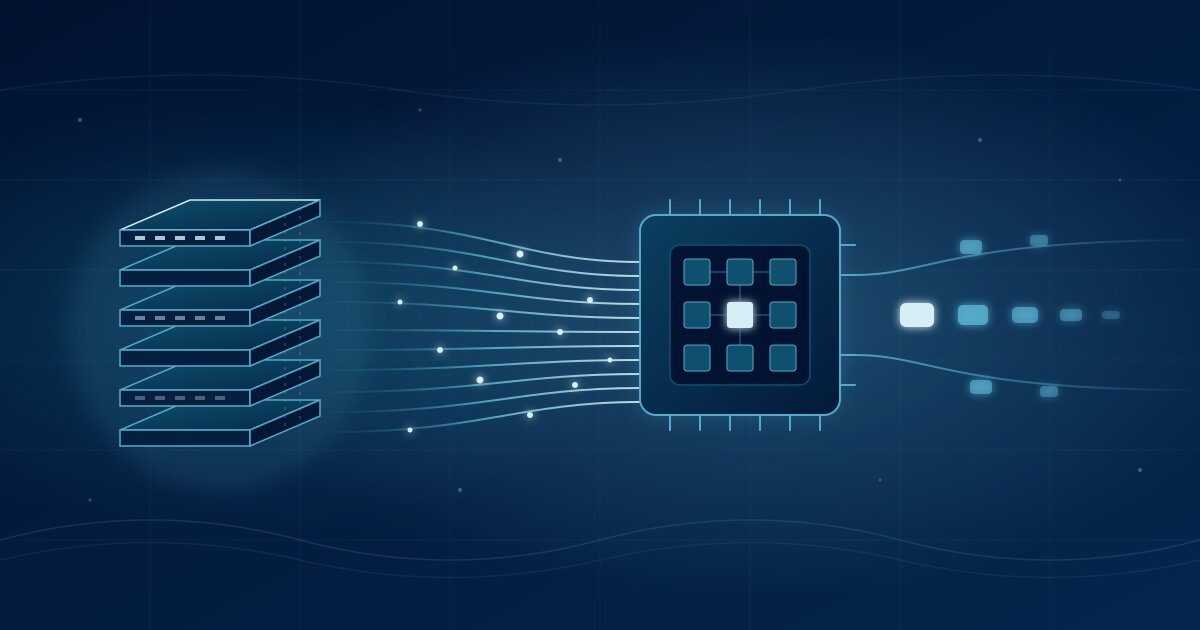
Language models generate text one token at a time. For each new token, the chip has to read the model's weights, often billions of numbers, from memory into its compute units. For a single user, the math performed on each weight is small. As a result, the processor spends much of its time waiting for data to arrive.
This makes text generation "memory-bound." The rate at which weights can be streamed from memory sets a ceiling on tokens per second. A rough rule of thumb is to divide a chip's memory bandwidth by the size of the model's weights in memory. The result is an upper limit on how many tokens per second a single request can produce.
Why bandwidth beats raw compute here
Chipmakers therefore pair AI accelerators with high-bandwidth memory (HBM). This memory is stacked close to the processor and moves far more data per second than conventional memory. More bandwidth means the weights reach the compute cores faster, so each token arrives sooner.
Raw compute still matters. It is especially important for reading a long prompt up front, because that work can be done in parallel. Once the model starts answering, however, bandwidth usually dominates.
Tricks that ease the bottleneck
Developers also tackle the problem in software. Quantization stores weights with fewer bits, so less data has to move for each token. Mixture-of-experts models activate only part of their parameters per token. That is why some large models can run surprisingly well on a single consumer graphics card. Batching many users together lets one read of the weights serve several requests at once, which raises total throughput.
The takeaway
For fast answers, how quickly a chip can feed it data matters as much as how much it can compute.
Sponsored Recommended for you – discover more →