Memory Bandwidth, Not Just Compute, Speeds Up AI Chatbots
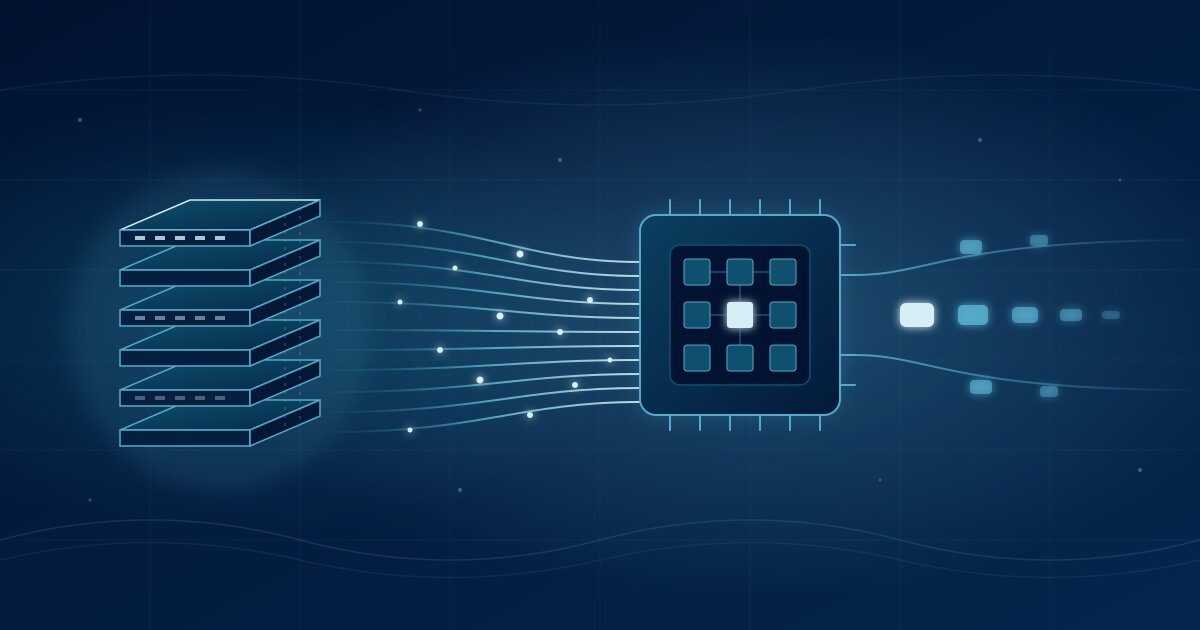
When a chatbot types out its answer word by word, the speed you see is often limited by how fast a chip can move data, not by how fast it can calculate. That is why memory bandwidth has become one of the most important specifications in AI hardware.
Every token needs the whole model
Language models generate text one token at a time. For each new token, the chip has to read the model's weights, often billions of numbers, from memory into its compute units. For a single user, the math performed on each weight is small. As a result, the processor spends much of its time waiting for data to arrive.
Sponsored Recommended for you – discover more →