
EmbeddingGemma 2: Google Adds Images, Audio and Video
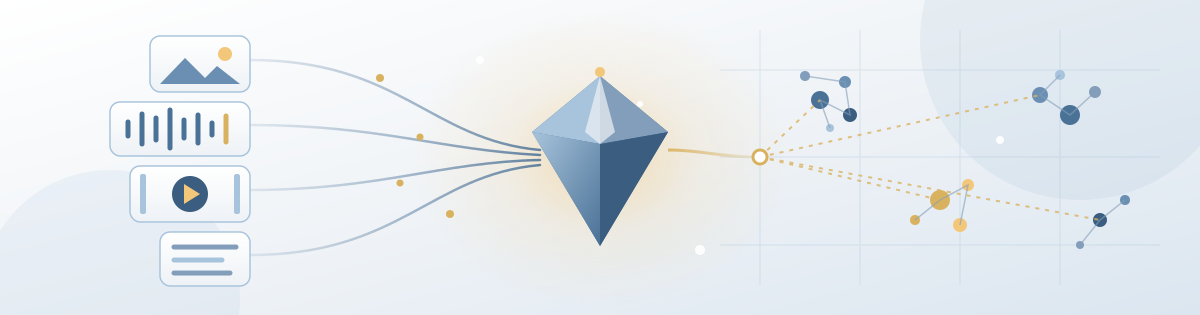
Google has released EmbeddingGemma 2, an open embedding model that now handles images, audio and video alongside text. It is still small enough to run on a smartphone.
An embedding model turns content into a list of numbers that captures its meaning. Similar items end up close together, which is what makes semantic search and retrieval work. The first EmbeddingGemma, introduced in September 2025, only worked with text. The new version places all four media types in one shared embedding space.
In practice, an app could take a spoken voice memo and find the matching moment in a video, and none of that data would have to leave the phone.
From text-only to multimodal
Google DeepMind research engineers Sahil Dua and Henrique Schechter Vera wrote in the announcement that the reaction to the original model "blew past our expectations." They put the download count at more than 20 million.
The new model is built on the Gemma 4 architecture Google released in April. At 740 million parameters, it is more than twice the size of its predecessor. Most of that extra weight sits in the vision and audio encoders, and apps that only process text can drop them. When Google tested a quantized build of the 270 million-parameter text core alone on a Google Pixel 11 Pro, it used about 191 megabytes of memory.
The storage question
Running the model is only part of the cost. Each embedding is a list of 768 numbers, and every indexed photo, clip or document adds another entry to a local vector database.
Google uses a training method called Matryoshka Representation Learning so developers can shorten those lists to as few as 128 numbers. That cuts storage by up to six times. According to Google's developer guide, at 256 numbers image, video and speech retrieval keep about 95% of their full-length quality.
Benchmarks: code leads
Code saw the largest gain. EmbeddingGemma 2 scored 78.68 on the code portion of the Massive Text Embedding Benchmark, almost 10 points higher than the first version. Google is aiming this at developers building retrieval for coding agents, a group that already includes people experimenting with local coding agents on consumer GPUs. Multilingual text scores, by contrast, barely changed.
Google also claims leading results among multimodal embedding models under 1 billion parameters. It says the model beats some specialist models more than twice its size on image, video and audio tasks.
Built to pair with Gemma 4
EmbeddingGemma 2 uses the same text tokenizer and audio encoder as Gemma 4. As a result, an on-device retrieval-augmented generation setup running both models needs less memory than two unrelated models would.
Google already runs the pair together in its AI Edge Foresight meeting app for Mac. In the AI Edge Gallery demo app, a feature called Video Moments Finder locates a scene inside a video from a typed or spoken query.
Availability
The weights are available now on Hugging Face and Google's Kaggle under an Apache 2.0 license, which allows commercial use. They already work with open-source serving tools including vLLM, llama.cpp and Ollama. Google said the model will come to the Model Garden in Gemini Enterprise Agent Platform soon.
Why It Matters
For developers, the most practical detail may be the modular design. Dropping the vision and audio encoders keeps text-only apps lean, while the shared components with Gemma 4 cut memory when the two models are used together. This suggests Google is treating on-device retrieval as a stack of parts rather than a single model release.
The release also fits a wider pattern of compact, task-specific open models built to support agents, such as AWS's small decision model. The code benchmark gain points in that direction too.
It is worth watching whether the multimodal claims hold up in independent tests, and whether developers accept the storage trade-offs that come with indexing large photo and video libraries on a phone.